Compute for the AI era
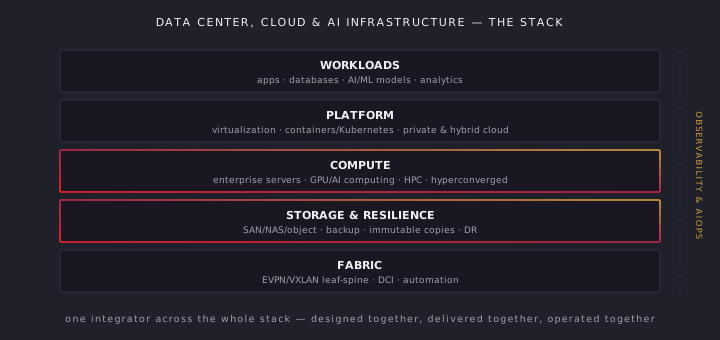
Enterprise servers, GPU/AI computing, hyperconverged and virtualized platforms, private and hybrid cloud — the platform layer designed as one system with the fabric beneath and the workloads above.
Everything this solution covers

Enterprise Servers
Rack, blade, and composable compute.

GPU / AI Computing & HPC
Accelerated infrastructure for AI/ML and analytics.

Data Center Architecture
Power, cooling, rack, and layout engineering.

Virtualization & HCI
Hyperconverged, software-defined compute + storage.

Private / Hybrid / Multi-Cloud
Cloud operating model on your terms.

Containers / Kubernetes
Platform engineering for modern apps.
Cloud Migration & Networking
Move safely; connect predictably.

Infrastructure Automation
IaC, orchestration, self-service.

Data Center Interconnect
Multi-site, active-active resilience.
How we think about it, and what good looks like
Design principles
- Right-size compute from measured workload profiles — CPU/GPU/memory ratios, not vendor defaults
- Accelerated infrastructure designed for the whole AI pipeline: GPU density, NVMe storage, low-latency fabric
- HCI where operational simplicity wins; disaggregated compute/storage where scale and economics demand it
- Power, cooling, and rack layout engineered for the density you’re actually going to run
Operating model
- Platform delivered with automation in place: templates, IaC, self-service, guardrails
- Kubernetes as the application platform — with the networking, storage, and security integrations that make it enterprise-grade
- Lifecycle management by design: firmware, hypervisor, and platform updates in tested rings
- Observability wired into the stack from day one
What good looks like
- New workload provisioned in minutes with policy inherited, not re-invented
- AI training and inference on infrastructure that keeps GPUs saturated instead of waiting on storage
- One team can operate compute, storage, and virtualization without vendor-by-vendor silos
- Capacity forecasts backed by telemetry — you buy the next node before you need it, not after
How we build it
Trained and certified on every platform in this solution area
Pre-sales design, implementation, and support — by engineers certified on the OEMs below.
A discipline, not a checklist
Compute is sized from measured workload profiles, not vendor defaults. Platforms are validated in a pilot ring, migrated per-service, and handed over with runbooks and training.
Discover
Your estate, measured — not assumed.
Design
Architecture mapped to your frameworks.
Deliver
Staged, parallel-run, rollback ready.
Operate
Hand-over — or our 24/7 managed ops.
Your environment is unique. The conversation is free.
Tell us what you’re building or defending — a professional, not a sales script, replies within one business day.